
What if your “random” bad days aren’t random at all?
Many of us blame bad luck, but small, repeatable clusters of triggers, like tight deadlines, short sleep, and skipped meals, often hide behind that feeling.
This post shows how to spot stress trigger clustering patterns, test whether a cluster is real (and not just coincidence), and run one simple experiment to see if changing a single link, like adding 30 minutes of sleep, shifts the whole chain.
You’ll get clear tracking steps and one action to try today.
What Are Recurring Groups Of Stressors?
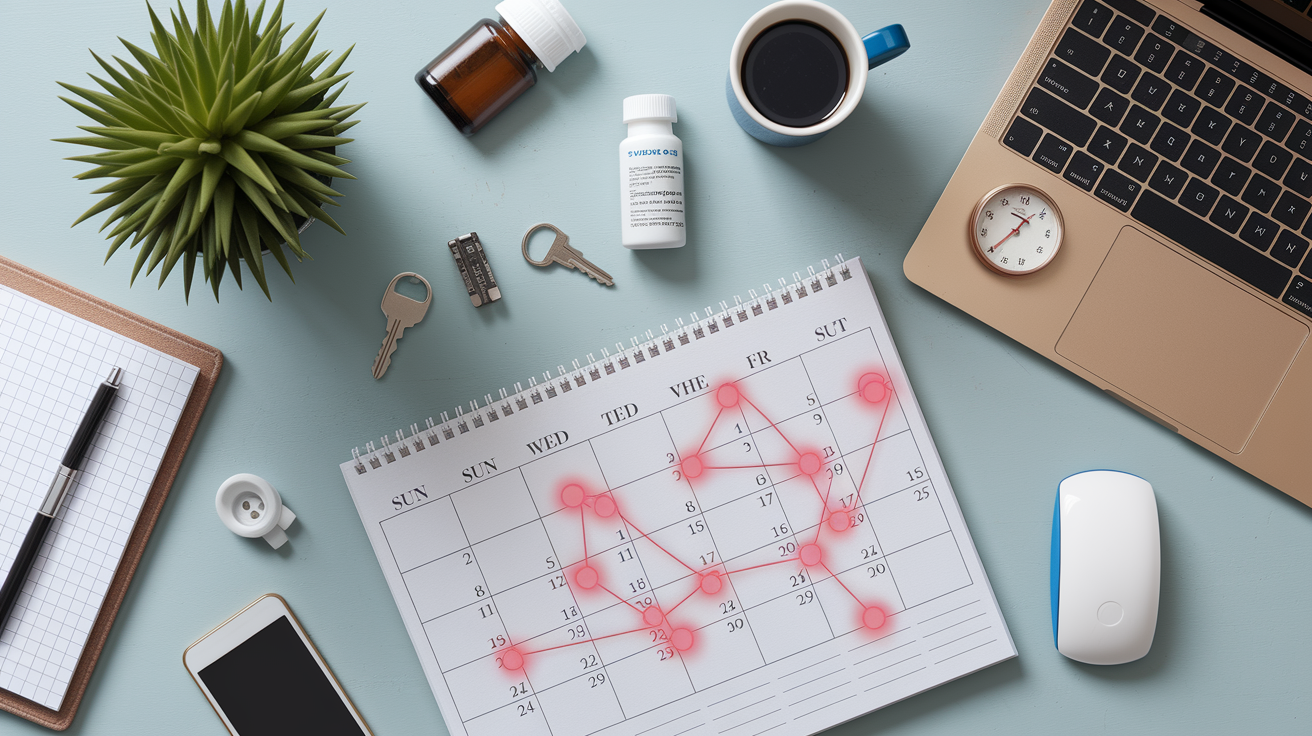
Stress trigger clustering patterns describe recurring groups or sequences of stressors that share a connection through timing, setting, situation, or behaviour. A cluster might show up as several triggers hitting at once, like a tight deadline, a sick kid, and a car repair all landing in the same week. Or it might look like a chain, where one stressor quietly sets up the next one, building a sequence that feels like a slow motion pileup.
Here’s the tricky part. Not every grouping of bad days is a real pattern. Genuine clusters usually show up again and again, or they’re backed by a behavioral feedback loop you can actually trace, like job loss leading to exhaustion, which delays budgeting, which creates debt, which strains a relationship. But sometimes it’s the clustering illusion at work, our brain’s habit of connecting dots that were never really linked. And with enough chances for coincidence, random events will bump into each other more often than feels logical. The birthday paradox is a classic example of this. In a group of just 23 people, there’s roughly a 50% chance two of them share a birthday, even though that feels wildly unlikely.
A few examples worth testing for yourself:
- Work deadlines, shortened sleep, and skipped meals recurring during month end reporting.
- Financial strain leading to delayed bills, relationship conflict, and further sleep disruption.
- Crowded commuting, sensory overload, and irritability appearing together on office days.
You can check these apparent patterns using statistical tests and clustering techniques, which we’ll walk through later.
What Causes Stress Triggers To Cluster Together?
Part of the answer is physiological. Chronic stress raises cortisol, and higher cortisol tends to crank up neural excitability while lowering your threshold for pain and stress responses. That combination can mess with your sleep wake cycle, which then feeds right back into more stress. A lot of people also notice something called the let down effect, where symptoms don’t show up during the peak of a stressful stretch but instead arrive once things calm down. So you push through a brutal week at work, then collapse with a headache or a cold the moment the weekend starts.
The other half of the story is behavioral and cognitive. One stressor often triggers the next in a feedback loop. Poor sleep leads to a short temper, which leads to conflict, which leads to even worse sleep. On top of that, our minds are wired with biases that make clustering feel more intense than it statistically is. Negativity bias makes bad events stick harder in memory. The availability heuristic makes recent or vivid stressors feel more common than they really are. And confirmation bias nudges us to notice events that fit a pattern we already suspect, while ignoring the ones that don’t.
Common real world trigger chains include:
- Poor sleep leading to irritability, which sparks conflict, which disrupts sleep again.
- Financial stress causing avoidance of bills, which snowballs into bigger financial stress.
- Skipped meals triggering low energy, which leads to poor decisions and added pressure later.
- Work overload causing shortened recovery time, which lowers tolerance for the next minor hassle.
Which Algorithms Group Stress Observations And Profiles?
Once you’ve got a collection of timestamped trigger logs, self reports, contextual notes, and maybe even physiological readings, the next step is turning that into something a clustering algorithm can actually work with, a feature matrix. This means cleaning up messy entries, deciding how to handle missing values (do you drop them, estimate them, or flag them separately), and encoding categorical context like “at work” or “at home” into a usable numeric form. You’ll also want to scale continuous features, like stress intensity ratings or hours of sleep, so no single variable dominates just because of its units. The goal is a clean set of variables representing things like intensity, behavior, setting, sleep quality, and physiology.
Once your data is ready, distance and similarity measures decide which observations get treated as alike. Euclidean distance works well for scaled continuous data, measuring the straight line gap between points. Manhattan distance is often a better fit when your data has larger, more erratic deviations, since it adds up differences along each dimension rather than measuring a direct line. For categorical or mixed data, you’ll need matching based measures or specialized mixed data metrics that can handle both numbers and categories at once.
| Method | How It Groups Observations | Best Use Case | Main Limitation |
|---|---|---|---|
| K-means | Assigns observations to the nearest centroid | Scaled numeric data with compact, clearly separated groups | Requires a chosen cluster count; handles irregular shapes poorly |
| Hierarchical clustering | Builds nested groups from pairwise similarities | Exploring tree-like relationships, comparing broad vs. narrow profiles | Sensitive to linkage and distance choices |
| DBSCAN | Forms dense groups and labels sparse observations as noise | Irregularly shaped groups, datasets with outliers | Depends strongly on density settings |
| Gaussian mixture models | Assigns probabilistic membership to overlapping distributions | Stress profiles that don’t fit hard categories | Relies on distributional assumptions and model selection |
Choosing between these methods comes down to a handful of practical questions. What type of features do you have? How many observations are you working with? Do you expect your groups to be round and separated, or messy and overlapping with noise mixed in? Is interpretability more important than precision, and do you even know how many groups you’re looking for ahead of time? It’s worth testing a few approaches side by side
Final Words
Start logging each stressful event with a timestamp, context, and a brief note on symptoms, that’s how pattern spotting begins. We defined what recurring stress clusters look like, why they form, compared methods that group similar observations, and showed how timing tests check whether recurrence beats chance.
Try a small experiment: track for a week, test one simple change, and compare what shifts.
With consistent logs and a few basic analyses you can turn fuzzy worries into clear stress trigger clustering patterns, and use them to guide one small, doable change today.
FAQ
Q: What are some examples of stress triggers and what are the common causes of stress?
A: Examples and common causes of stress include acute events (deadlines, conflicts), ongoing pressures (financial strain, caregiving), lifestyle factors (poor sleep, long commutes), and health or job changes that pile up over time.
Q: What are the 7 types of stress?
A: The seven types of stress often described are acute, episodic acute, chronic, traumatic, anticipatory, physical, and eustress (short-term positive stress).
Q: What are 14 medical conditions that can be caused or worsened by stress?
A: Fourteen medical conditions that can be caused or worsened by stress include cardiovascular disease, high blood pressure, stroke, anxiety, depression, insomnia, migraines, irritable bowel syndrome, acid reflux, asthma flares, eczema, psoriasis, autoimmune flares, and poorer blood sugar control.